The primary bottleneck in serving Large Language Models is not raw compute power; it is memory bandwidth. During standard autoregressive decoding, generating each token requires streaming hundreds of gigabytes of model weights from High Bandwidth Memory (HBM) into the GPU compute cores just to compute a single matrix-vector multiplication.
As a result, modern GPUs run at single-digit arithmetic intensity during inference, severely underutilizing their Tensor Cores.
Speculative Decoding solves this by trading compute for memory efficiency, allowing models to generate 2 to 3 tokens per memory transfer with zero degradation in output quality.
The Mathematical Intuition of Speculative Decoding
Standard decoding is strictly serial: $$x_{t} \sim P(x | x_{<t})$$
In speculative decoding, we introduce a lightweight Draft Model $M_q$ (e.g. a 1B model) alongside our massive Target Model $M_p$ (e.g. a 70B model):
- Draft Phase: The fast draft model predicts $K$ future tokens speculatively in a burst ($x_{t+1}, x_{t+2}, \dots, x_{t+K}$). Because the draft model is tiny, this takes mere milliseconds.
- Verification Phase: The target model runs a single parallel forward pass on all $K+1$ candidate tokens simultaneously.
- Acceptance Criterion: Using modified rejection sampling, the target model accepts tokens matching its probability distribution. If the target model accepts 3 out of 4 tokens, we generate 3 tokens in the time of 1 target forward pass!
Speculative Decoding Sequence:
Draft Model (Fast):   [Token 1] ───> [Token 2] ───> [Token 3] ───> [Token 4]
                             │              │              │              │
Target Model (1 Pass): [Verify 1: ✓]  [Verify 2: ✓]  [Verify 3: ✓]  [Verify 4: ✗ (Resampled)]
Medusa: Speculative Decoding Without a Separate Draft Model
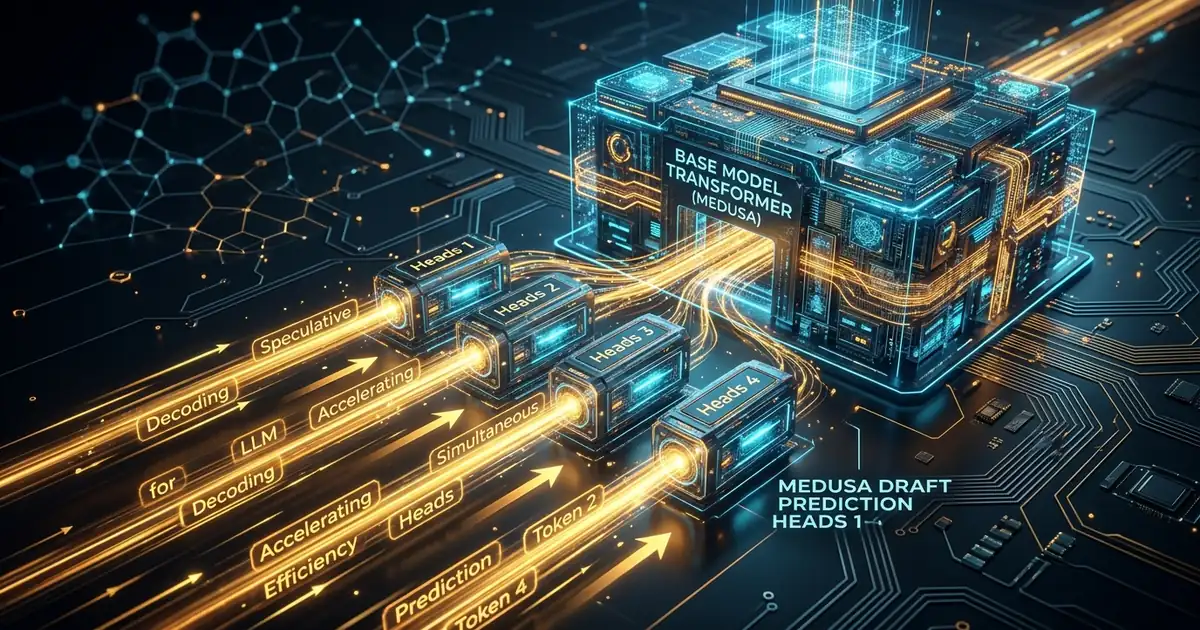
While classical speculative decoding requires managing two models in memory, Medusa introduces extra decoding heads directly on top of the original model's final hidden state.
Each Medusa head is a lightweight feedforward layer trained to predict subsequent token offsets:
- Head 0 predicts $t+1$
- Head 1 predicts $t+2$
- Head 2 predicts $t+3$
By using a tree-structured attention mask, Medusa generates candidate token trees and verifies them in a single step, boosting generation speeds by 2.2x to 2.8x on models like Llama 3 70B with zero additional model management overhead.
Production Implementation with vLLM / TensorRT-LLM
Both vLLM and TensorRT-LLM feature out-of-the-box support for speculative decoding:
# Serving Llama 3.3 70B with Llama 3.2 1B as Speculative Drafter
python3 -m vllm.entrypoints.openai.api_server \
    --model meta-llama/Llama-3.3-70B-Instruct \
    --speculative-model meta-llama/Llama-3.2-1B-Instruct \
    --num-speculative-tokens 5 \
    --gpu-memory-utilization 0.92 \
    --tensor-parallel-size 4
Economic Impact on Infrastructure Budgets
For a company processing 100 million tokens daily:
- Standard generation throughput: 45 tokens/sec per GPU.
- Speculative decoding throughput: 105 tokens/sec per GPU.
- Hardware requirement drops from 16x H100 GPUs to 8x H100 GPUs, cutting monthly cloud hosting expenditure in half.