Cloud-hosted AI has an inescapable economic and privacy reality: every token costs money, and every query leaves the user's device. For applications handling sensitive financial documents, private notes, or medical records, routing queries to centralized APIs is often unacceptable.
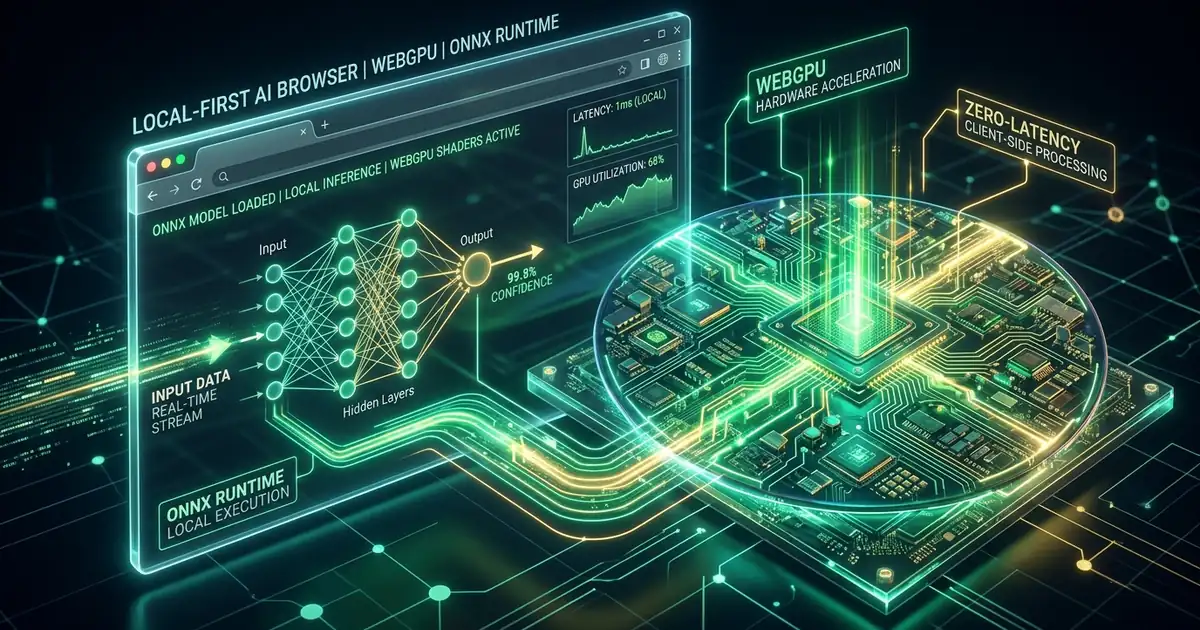
Enter Local-First Web AI. With the maturation of the WebGPU API across modern browsers and the optimization of ONNX Runtime Web (and WebLLM), web applications can now execute quantized language models (from 1.5B to 7B parameters) directly on the client's GPU with hardware-accelerated shaders.
The WebGPU Pipeline: Direct Silicon Access in JS
WebGPU provides modern, low-overhead access to the underlying graphics hardware (Direct3D 12, Metal, Vulkan). Unlike WebGL, which was constrained to graphics shaders, WebGPU features dedicated Compute Shaders capable of general-purpose matrix multiplications.
Client Browser Architecture:
┌─────────────────────────────────────────────────────────────┐
│                       Browser Tab                           │
│  ┌───────────────────────┐       ┌───────────────────────┐  │
│  │   React / Next.js UI  │<─────>│  Web Worker (Wasm)    │  │
│  └───────────────────────┘       └──────────┬────────────┘  │
│                                             │               │
│                                  ┌──────────▼────────────┐  │
│                                  │   ONNX Runtime Web    │  │
│                                  │   (WebGPU EP Backend) │  │
│                                  └──────────┬────────────┘  │
└─────────────────────────────────────────────┼───────────────┘
                                              │ WGPU Compute Pipeline
                                              ▼
                             ┌────────────────────────────────┐
                             │ Host GPU (Apple M-Series /     │
                             │ NVIDIA RTX / Intel Arc)        │
                             └────────────────────────────────┘
Step-by-Step Implementation: In-Browser Text Embedding
Here is how to run client-side vector embedding using ONNX Runtime Web:
import * as ort from 'onnxruntime-web/webgpu';

// Configure WebGPU Execution Provider
ort.env.wasm.numThreads = 4;
ort.env.wasm.proxy = true;

async function loadLocalEmbeddingSession() {
    console.log('⚡ Initializing WebGPU ONNX Session...');
    const session = await ort.InferenceSession.create(
        '/models/bge-small-en-v1.5-quant.onnx',
        { executionProviders: ['webgpu'] }
    );
    console.log('✅ Model loaded directly into VRAM');
    return session;
}

async function computeEmbedding(session, tokenIds, attentionMask) {
    const feeds = {
        input_ids: new ort.Tensor('int64', BigInt64Array.from(tokenIds.map(BigInt)), [1, tokenIds.length]),
        attention_mask: new ort.Tensor('int64', BigInt64Array.from(attentionMask.map(BigInt)), [1, attentionMask.length])
    };

    const results = await session.run(feeds);
    const embedding = results.last_hidden_state.data;
    return embedding;
}
Real-World Performance & Business Implications
On modern consumer laptops:
- Apple M3 / M4: DeepSeek-R1-Distill-1.5B runs at 42 tokens/sec entirely in the browser.
- Intel Core Ultra (Meteor Lake NPU/iGPU): Runs quantized Phi-3.5 at 22 tokens/sec.
- Zero Server Costs: A SaaS product with 1,000,000 daily users running client-side local models pays $0.00 in inference API bills.
- Offline Capabilities: Full offline functionality on trains, airplanes, and air-gapped workstations.